Scene-level 3D object detection
We evaluate the reconstruction stage of Mundo as a scene-level, class-agnostic 3D object detector in the setting of Boxer [1]. On the ten CA-1M validation sequences used by Boxer, Mundo reaches F1 0.498 at IoU 0.25 from RGB frames alone, against 0.400 for the strongest baseline (CuTR RGB-D).
Setup
- Data. The ten CA-1M validation sequences listed in the Boxer appendix [1] (45662921, 45261179, 47115543, 45261143, 45261615, 42897545, 45261133, 42897552, 45663113, 42897521, with 629 frames and 856 target objects) and the ADT sequence Apartment_release_work_seq106_M1292 (1WM103600M1292_optitrack_release_work_seq106 in the Boxer appendix, with 92 frames and 135 static target objects). NymeriaPlus is not included yet.
- Frames. We take one frame per second, the one closest to each whole second of the capture. Every method receives the same frames, and sequence IDs and timestamps are stored with the inputs.
- Inputs. Track A gives GT camera poses and sensor depth (laser-registered poses with ARKit LiDAR depth on CA-1M, GT poses and depth on ADT), the RGB-D input of Boxer. Track B gives RGB only, with poses and depth from Pi3X, one shared geometry per sequence for all methods, and all boxes are mapped to the GT world by one similarity per sequence fitted on depth (Pi3X scale 0.90–1.10, 2–5 cm residual). In track B the baselines also receive the true gravity direction, as an IMU would provide, while Mundo estimates gravity itself.
- Ground truth. World-level boxes of the objects visible in the evaluated frames. CA-1M follows the CA-1M loader of Boxer, so floor, wall and shelter boxes and boxes with a side over 3 m are ignored, and thin sides of GT and predictions are expanded to 5 cm. ADT follows the ADT loader of Boxer, so a static object is a target if, in at least one frame, its visibility is at least 0.3, its 2D box is at least 2% of the image and its centre is within 5 m of the camera. Every other observed object is ignored.
- Metrics. Class-agnostic precision, recall and F1 at 3D IoU 0.25 and 0.5, with one-to-one Hungarian matching of oriented boxes. A prediction on an ignored object is neither a true nor a false positive. Dataset numbers pool all matches over the sequences.
- Baselines. Boxer [1] runs the official OWLv2 detector with the LVIS+ prompts, BoxerNet and the offline fusion. CuTR [2] runs its own detector with the RGB-D and the RGB model, and its per-frame boxes are fused with the Boxer fusion. SpatialLM 1.1 [3] reads the coloured point cloud of the same frames. For Boxer and CuTR we report the official fusion, the score threshold that maximises F1 on the four dev sequences, and, as an upper bound for the baselines, the threshold that maximises F1 on the test sequences.
- Mundo. The reconstruction stage of the release (0.7.0rc3) with one configuration for every sequence and both tracks, namely the request “give every distinct physical object its own box” and Boxer lifts kept from a single view. The single-view setting was chosen on four further CA-1M validation sequences that are not part of the test set. Proxy mode, the default for video generation, is reported in the ablation.
- Protocol. Boxer has not released its frame lists or scoring code, so all numbers here are re-run under this unified protocol. The reproduction check at the end compares the baselines' mAP with the published values.
Results on CA-1M
Mundo leads in both tracks and at both IoU thresholds. With GT poses and depth (track A) it reaches F1 0.508 at IoU 0.25, against 0.461 for CuTR RGB-D, which is trained on CA-1M. From RGB alone (track B) the margin grows to 9.8 points. Boxer and CuTR are listed with the official fusion, with a threshold chosen on the dev split and with the test-oracle threshold, and bold marks the best F1 in each column. A paired bootstrap over the ten sequences confirms the margins. The 95% interval of the F1 difference excludes zero against every baseline operating point in both tracks and at both thresholds, with one exception, CuTR RGB-D at its test-oracle threshold at IoU 0.5 in track A (+0.013, interval -0.013 to +0.044). With the threshold chosen on the dev split the same comparison gives +0.029 (+0.001 to +0.055).
| Method | Operating point | A · GT pose + sensor depth | B · estimated pose + depth (RGB only) | ||||||
|---|---|---|---|---|---|---|---|---|---|
| P | R | F1 | F1.5 | P | R | F1 | F1.5 | ||
| SpatialLM [3] | coloured point cloud | 0.330 | 0.040 | 0.071 | 0.029 | 0.483 | 0.050 | 0.091 | 0.028 |
| CuTR RGB [2] | official fusion | 0.701 | 0.110 | 0.190 | 0.093 | 0.567 | 0.084 | 0.146 | 0.075 |
| CuTR RGB [2] | threshold chosen on dev | 0.223 | 0.269 | 0.244 | 0.093 | 0.142 | 0.242 | 0.179 | 0.072 |
| CuTR RGB [2] | test-oracle threshold | 0.203 | 0.332 | 0.252 | 0.099 | 0.142 | 0.242 | 0.179 | 0.072 |
| CuTR RGB-D [2] | official fusion | 0.918 | 0.196 | 0.323 | 0.191 | 0.848 | 0.196 | 0.319 | 0.175 |
| CuTR RGB-D [2] | threshold chosen on dev | 0.520 | 0.415 | 0.461 | 0.244 | 0.439 | 0.368 | 0.400 | 0.178 |
| CuTR RGB-D [2] | test-oracle threshold | 0.520 | 0.415 | 0.461 | 0.260 | 0.439 | 0.368 | 0.400 | 0.184 |
| Boxer [1] | official fusion | 0.801 | 0.244 | 0.374 | 0.227 | 0.760 | 0.229 | 0.352 | 0.214 |
| Boxer [1] | single-view support | 0.343 | 0.508 | 0.410 | 0.212 | 0.312 | 0.456 | 0.371 | 0.176 |
| Boxer [1] | threshold chosen on dev | 0.441 | 0.419 | 0.430 | 0.224 | 0.392 | 0.371 | 0.381 | 0.176 |
| Boxer [1] | test-oracle threshold | 0.441 | 0.419 | 0.430 | 0.224 | 0.392 | 0.371 | 0.381 | 0.176 |
| Mundo (ours) | mean ± std over 3 runs | 0.584 ±0.004 | 0.449 ±0.007 | 0.508 ±0.005 | 0.273 ±0.004 | 0.571 ±0.001 | 0.442 ±0.002 | 0.498 ±0.001 | 0.239 ±0.005 |
Paired bootstrap on CA-1M
F1 of Mundo minus F1 of each baseline operating point, pooled over the ten sequences, with the 95% interval from 10,000 resamples of the sequences.
| Baseline | A · IoU 0.25 | A · IoU 0.5 | B · IoU 0.25 | B · IoU 0.5 |
|---|---|---|---|---|
| Boxer (official) | +0.133 +0.080 to +0.210 | +0.045 +0.012 to +0.086 | +0.146 +0.107 to +0.205 | +0.026 +0.002 to +0.054 |
| Boxer (single-view) | +0.098 +0.069 to +0.134 | +0.061 +0.040 to +0.082 | +0.128 +0.090 to +0.163 | +0.063 +0.039 to +0.089 |
| Boxer (dev threshold) | +0.078 +0.043 to +0.110 | +0.049 +0.019 to +0.071 | +0.117 +0.073 to +0.156 | +0.063 +0.039 to +0.084 |
| Boxer (test-oracle threshold) | +0.078 +0.043 to +0.110 | +0.049 +0.019 to +0.071 | +0.117 +0.073 to +0.156 | +0.063 +0.039 to +0.084 |
| CuTR RGB-D (official) | +0.184 +0.117 to +0.266 | +0.082 +0.052 to +0.123 | +0.180 +0.120 to +0.249 | +0.065 +0.039 to +0.090 |
| CuTR RGB-D (dev threshold) | +0.046 +0.010 to +0.086 | +0.029 +0.001 to +0.055 | +0.098 +0.046 to +0.138 | +0.061 +0.029 to +0.084 |
| CuTR RGB-D (test-oracle threshold) | +0.046 +0.010 to +0.086 | +0.013 -0.013 to +0.044 | +0.098 +0.046 to +0.138 | +0.055 +0.018 to +0.082 |
Results on ADT
ADT seq106 has 135 static target objects in one apartment. Mundo leads at IoU 0.25 in both tracks and is on par with Boxer at IoU 0.5 in track A (0.189 against 0.186).
| Method | Operating point | A · GT pose + sensor depth | B · estimated pose + depth (RGB only) | ||||||
|---|---|---|---|---|---|---|---|---|---|
| P | R | F1 | F1.5 | P | R | F1 | F1.5 | ||
| SpatialLM [3] | coloured point cloud | 0.444 | 0.059 | 0.105 | 0.078 | 0.273 | 0.044 | 0.076 | 0.025 |
| CuTR RGB [2] | official fusion | 0.081 | 0.022 | 0.035 | 0.000 | 0.027 | 0.007 | 0.012 | 0.000 |
| CuTR RGB [2] | threshold chosen on dev | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 | 0.000 |
| CuTR RGB [2] | test-oracle threshold | 0.005 | 0.037 | 0.009 | 0.000 | 0.003 | 0.022 | 0.005 | 0.000 |
| CuTR RGB-D [2] | official fusion | 0.364 | 0.089 | 0.143 | 0.083 | 0.265 | 0.067 | 0.107 | 0.059 |
| CuTR RGB-D [2] | threshold chosen on dev | 0.262 | 0.319 | 0.288 | 0.079 | 0.161 | 0.200 | 0.178 | 0.052 |
| CuTR RGB-D [2] | test-oracle threshold | 0.319 | 0.281 | 0.299 | 0.080 | 0.161 | 0.200 | 0.178 | 0.053 |
| Boxer [1] | official fusion | 0.457 | 0.119 | 0.188 | 0.106 | 0.371 | 0.096 | 0.153 | 0.106 |
| Boxer [1] | single-view support | 0.313 | 0.311 | 0.312 | 0.186 | 0.206 | 0.237 | 0.221 | 0.097 |
| Boxer [1] | threshold chosen on dev | 0.378 | 0.207 | 0.268 | 0.172 | 0.213 | 0.148 | 0.175 | 0.105 |
| Boxer [1] | test-oracle threshold | 0.322 | 0.274 | 0.296 | 0.176 | 0.224 | 0.222 | 0.223 | 0.108 |
| Mundo (ours) | mean ± std over 3 runs | 0.449 ±0.027 | 0.314 ±0.013 | 0.369 ±0.017 | 0.189 ±0.011 | 0.305 ±0.012 | 0.242 ±0.003 | 0.270 ±0.005 | 0.113 ±0.003 |
Where the gain comes from
Mundo starts from Boxer lifts on its own geometry and from SAM3 masks fused in 3D. The agent keeps, merges, corrects and adds boxes against the photographs. On CA-1M track B it raises precision from 0.354 to 0.571 while recall moves from 0.471 to 0.442, and F1 at IoU 0.25 from 0.404 to 0.498. With the official four-view support of Boxer most lifts are discarded at 1 Hz, and keeping single-view lifts adds 3.2 points of F1 at IoU 0.5. Proxy mode keeps only the main bodies, with high precision and few small objects.
CA-1M
| Method | Operating point | A · GT pose + sensor depth | B · estimated pose + depth (RGB only) | ||||||
|---|---|---|---|---|---|---|---|---|---|
| P | R | F1 | F1.5 | P | R | F1 | F1.5 | ||
| Boxer lifts | scene vocabulary, single-view support | 0.433 ±0.005 | 0.438 ±0.010 | 0.436 ±0.002 | 0.243 ±0.006 | 0.389 ±0.007 | 0.400 ±0.001 | 0.395 ±0.004 | 0.210 ±0.002 |
| SAM3 masks fused in 3D | proposals | 0.407 ±0.005 | 0.321 ±0.003 | 0.359 ±0.003 | 0.123 ±0.003 | 0.438 ±0.005 | 0.341 ±0.006 | 0.383 ±0.006 | 0.137 ±0.003 |
| Merged proposals | input to the agent | 0.364 ±0.004 | 0.483 ±0.007 | 0.415 ±0.003 | 0.222 ±0.006 | 0.354 ±0.005 | 0.471 ±0.003 | 0.404 ±0.004 | 0.196 ±0.002 |
| Full pipeline with the agent | mean ± std over 3 runs | 0.584 ±0.004 | 0.449 ±0.007 | 0.508 ±0.005 | 0.273 ±0.004 | 0.571 ±0.001 | 0.442 ±0.002 | 0.498 ±0.001 | 0.239 ±0.005 |
| Full, official four-view support | Boxer lifts mostly dropped at 1 Hz | 0.532 | 0.391 | 0.451 | 0.209 | 0.557 | 0.419 | 0.478 | 0.207 |
| Full, proxy mode | no detection request | 0.743 | 0.193 | 0.306 | 0.210 | 0.751 | 0.204 | 0.321 | 0.197 |
ADT
| Method | Operating point | A · GT pose + sensor depth | B · estimated pose + depth (RGB only) | ||||||
|---|---|---|---|---|---|---|---|---|---|
| P | R | F1 | F1.5 | P | R | F1 | F1.5 | ||
| Boxer lifts | scene vocabulary, single-view support | 0.352 ±0.012 | 0.242 ±0.013 | 0.287 ±0.012 | 0.146 ±0.011 | 0.216 ±0.014 | 0.160 ±0.007 | 0.184 ±0.007 | 0.116 ±0.000 |
| SAM3 masks fused in 3D | proposals | 0.449 ±0.021 | 0.326 ±0.016 | 0.378 ±0.018 | 0.132 ±0.010 | 0.290 ±0.019 | 0.230 ±0.006 | 0.256 ±0.011 | 0.074 ±0.002 |
| Merged proposals | input to the agent | 0.343 ±0.010 | 0.375 ±0.013 | 0.358 ±0.011 | 0.144 ±0.008 | 0.211 ±0.016 | 0.242 ±0.003 | 0.225 ±0.010 | 0.094 ±0.000 |
| Full pipeline with the agent | mean ± std over 3 runs | 0.449 ±0.027 | 0.314 ±0.013 | 0.369 ±0.017 | 0.189 ±0.011 | 0.305 ±0.012 | 0.242 ±0.003 | 0.270 ±0.005 | 0.113 ±0.003 |
| Full, official four-view support | Boxer lifts mostly dropped at 1 Hz | 0.453 | 0.289 | 0.353 | 0.208 | 0.318 | 0.259 | 0.286 | 0.114 |
| Full, proxy mode | no detection request | 0.629 | 0.163 | 0.259 | 0.188 | 0.447 | 0.126 | 0.197 | 0.139 |
Recall by object size
Recall at IoU 0.25 by GT volume on CA-1M, track B (small under 0.01 m³, large over 0.1 m³). Small objects such as switches, bottles and frames make up half of the CA-1M targets and remain the main source of misses for every method.
| Method | small <0.01 m³ | medium | large >0.1 m³ |
|---|---|---|---|
| SpatialLM | 0.002 | 0.036 | 0.198 |
| CuTR RGB-D, official fusion | 0.123 | 0.239 | 0.323 |
| Boxer, official fusion | 0.114 | 0.291 | 0.437 |
| Boxer, single-view support | 0.345 | 0.514 | 0.659 |
| Mundo proposals (before the agent) | 0.382 ±0.005 | 0.497 ±0.005 | 0.665 ±0.005 |
| Mundo (ours) | 0.364 ±0.006 | 0.449 ±0.012 | 0.639 ±0.006 |
Scenes in 3D
Four sequences in track B (estimated geometry), namely the three CA-1M sequences with the largest F1 margin of Mundo over the strongest baseline, and the ADT sequence. Points show the reconstructed geometry of the evaluated frames, shaded by height. Baseline boxes are shown at their best-F1 thresholds. Drag to orbit and use +/− or ctrl+wheel to zoom.
59 frames at 1 Hz and 60 GT objects, track B (estimated geometry). F1 at IoU 0.25 is 0.74 for Mundo (mean of 3 runs, the run with the median F1 is shown) and 0.55 for the strongest baseline.
70 frames at 1 Hz and 83 GT objects, track B (estimated geometry). F1 at IoU 0.25 is 0.55 for Mundo (mean of 3 runs, the run with the median F1 is shown) and 0.43 for the strongest baseline.
115 frames at 1 Hz and 190 GT objects, track B (estimated geometry). F1 at IoU 0.25 is 0.42 for Mundo (mean of 3 runs, the run with the median F1 is shown) and 0.30 for the strongest baseline.
92 frames at 1 Hz and 135 GT objects, track B (estimated geometry). F1 at IoU 0.25 is 0.27 for Mundo (mean of 3 runs, the run with the median F1 is shown) and 0.22 for the strongest baseline.
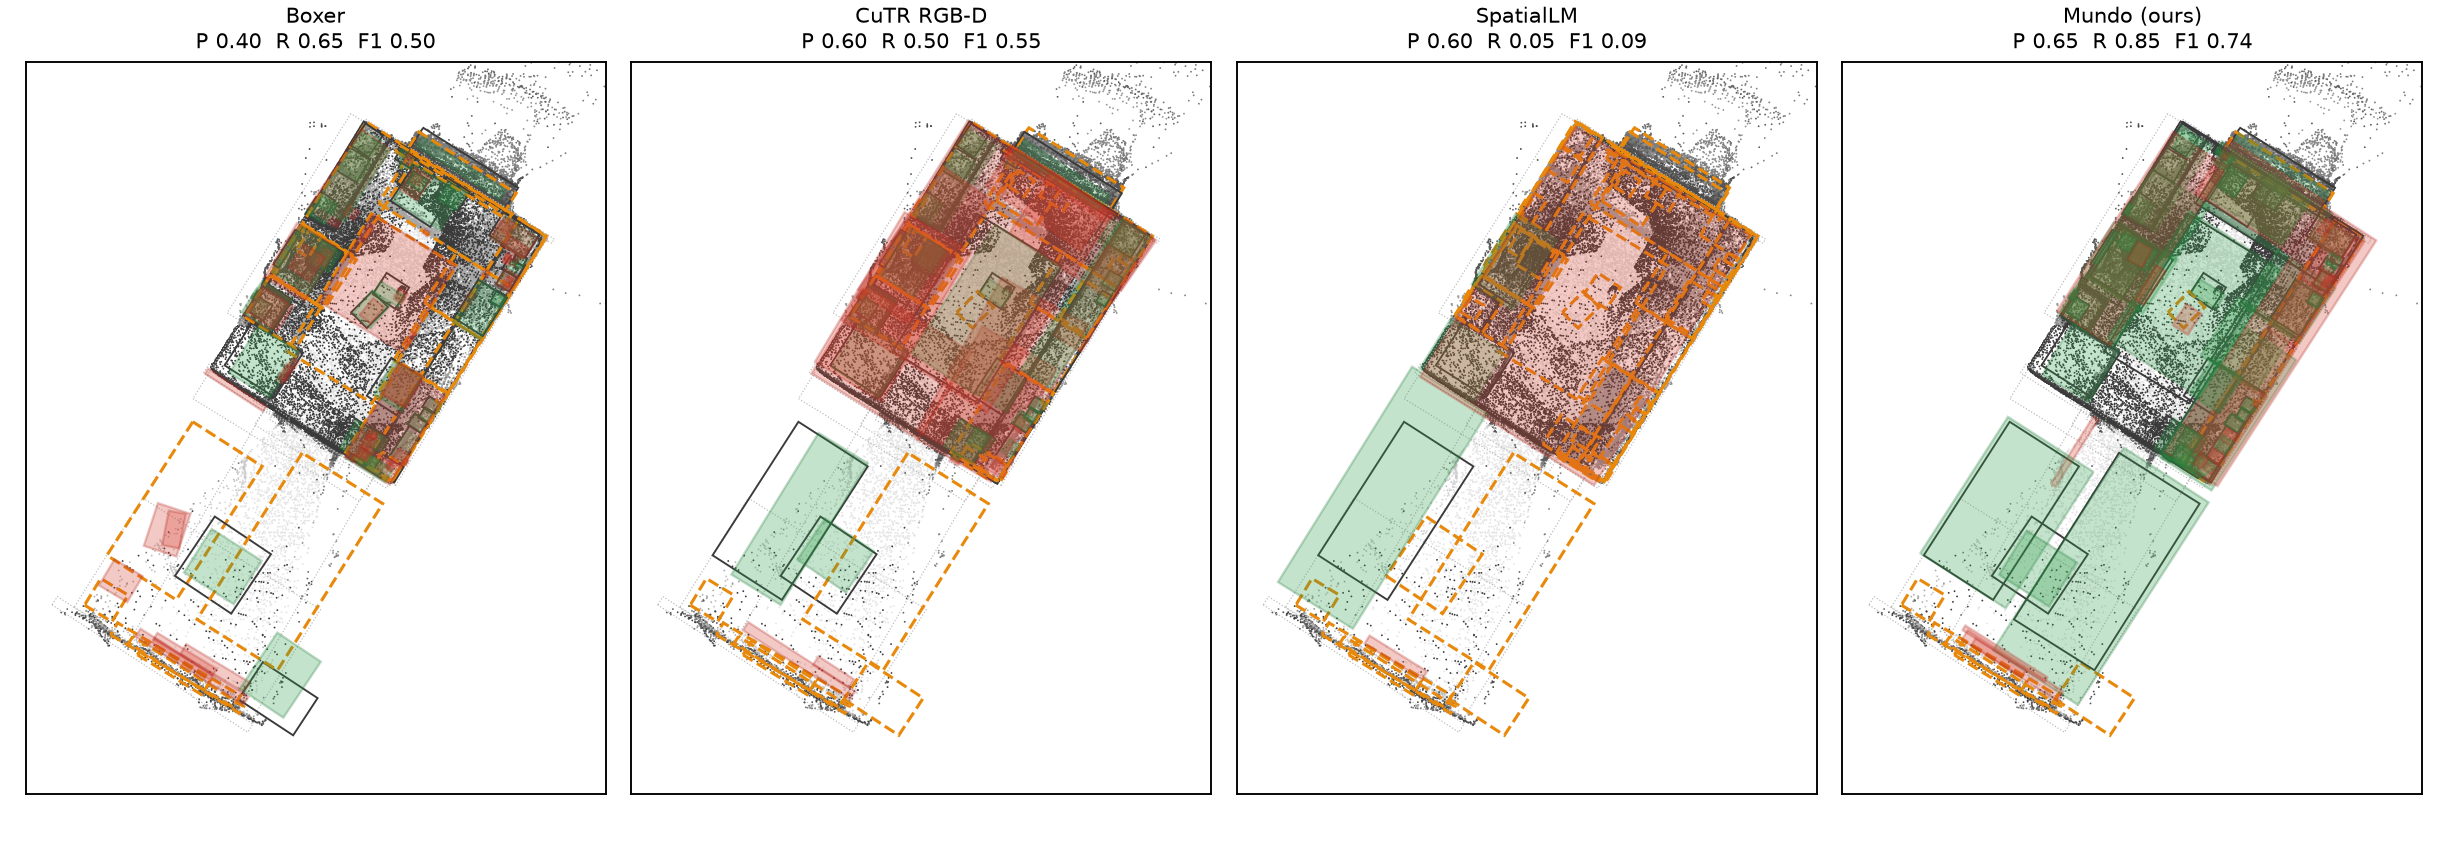
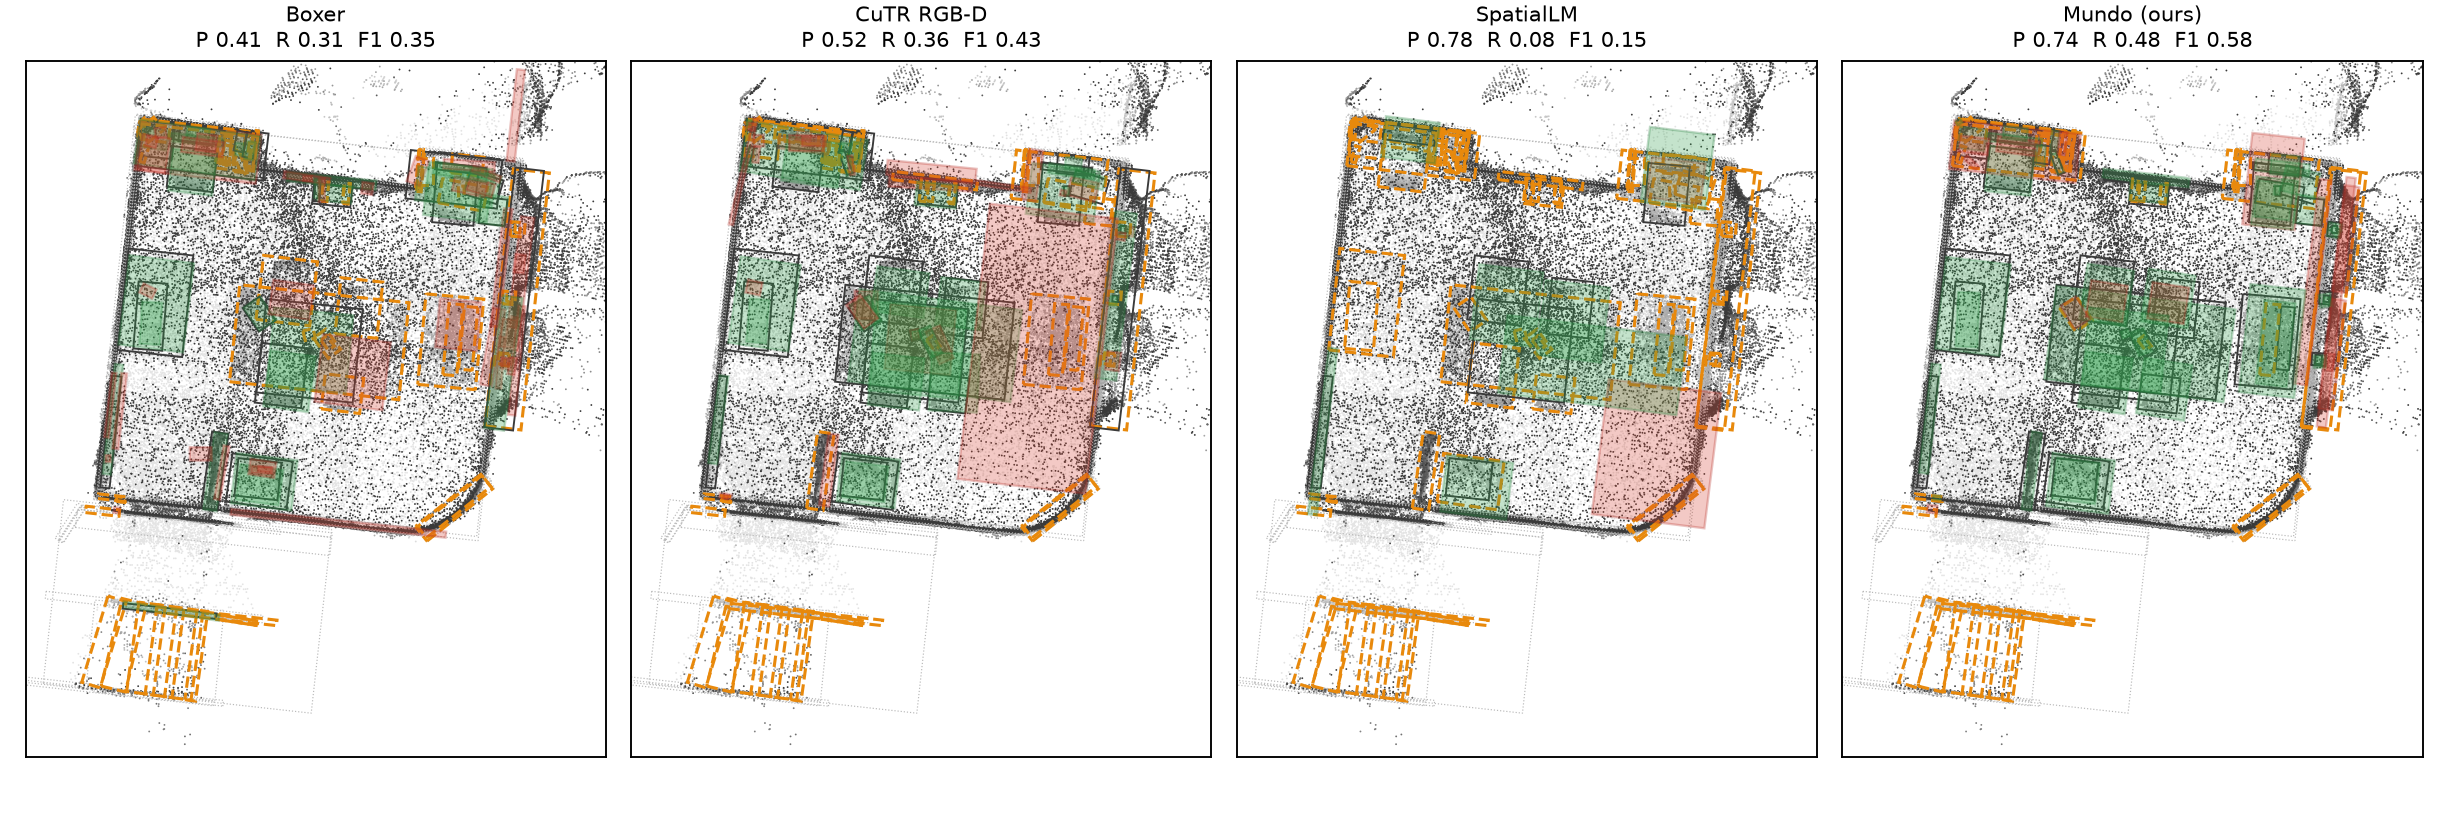
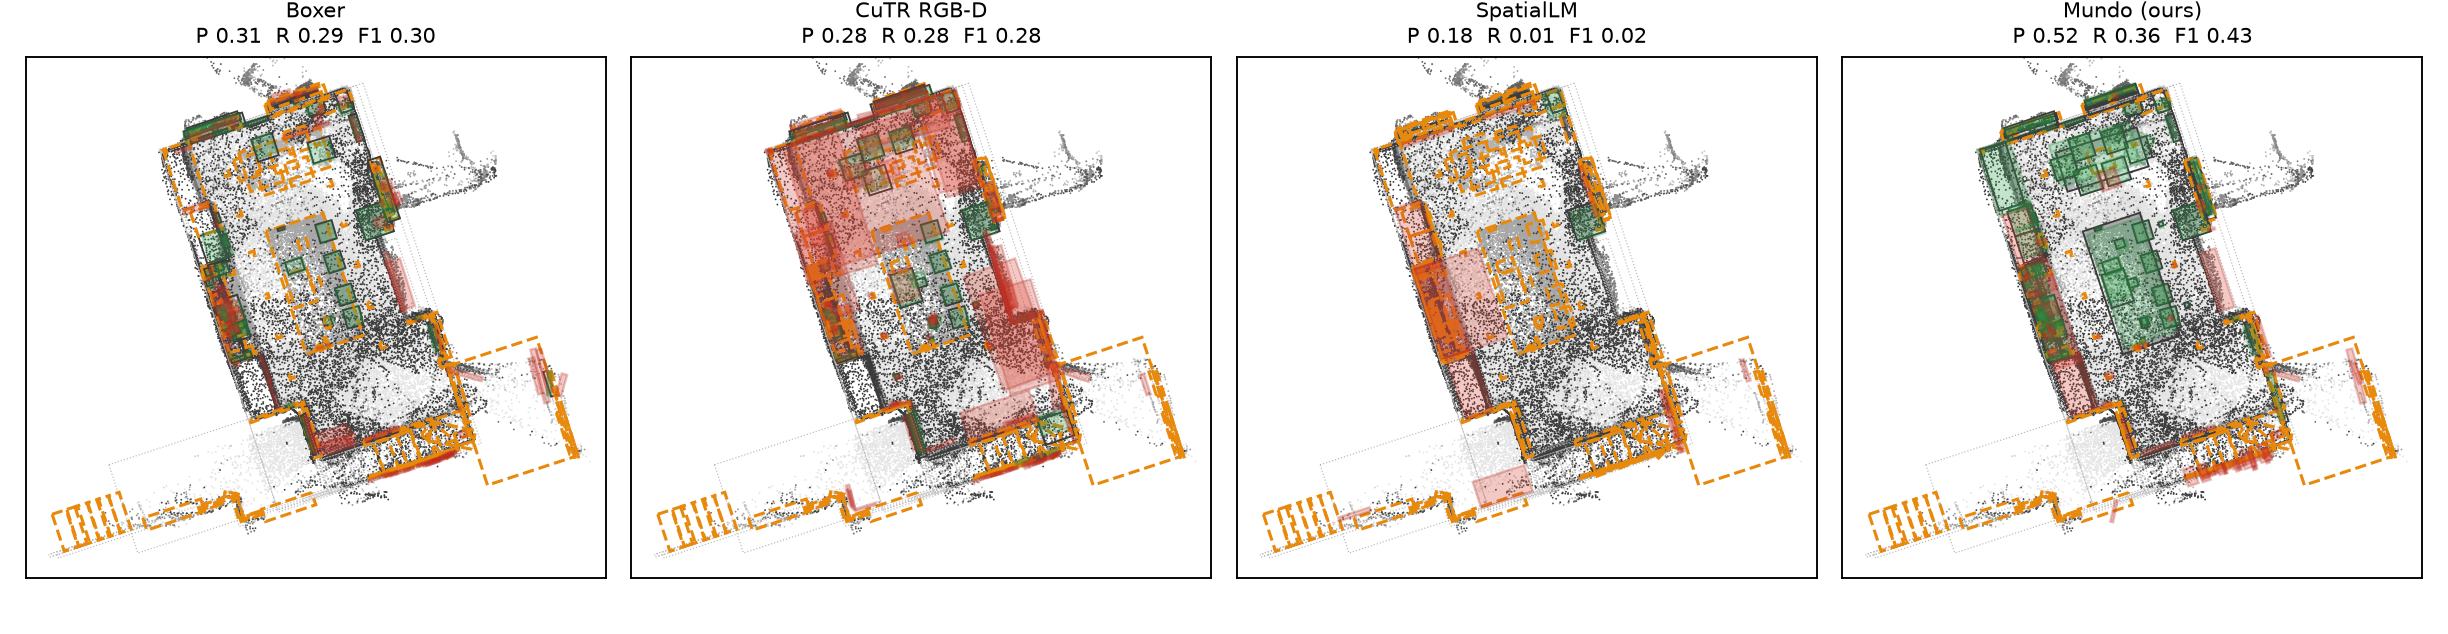
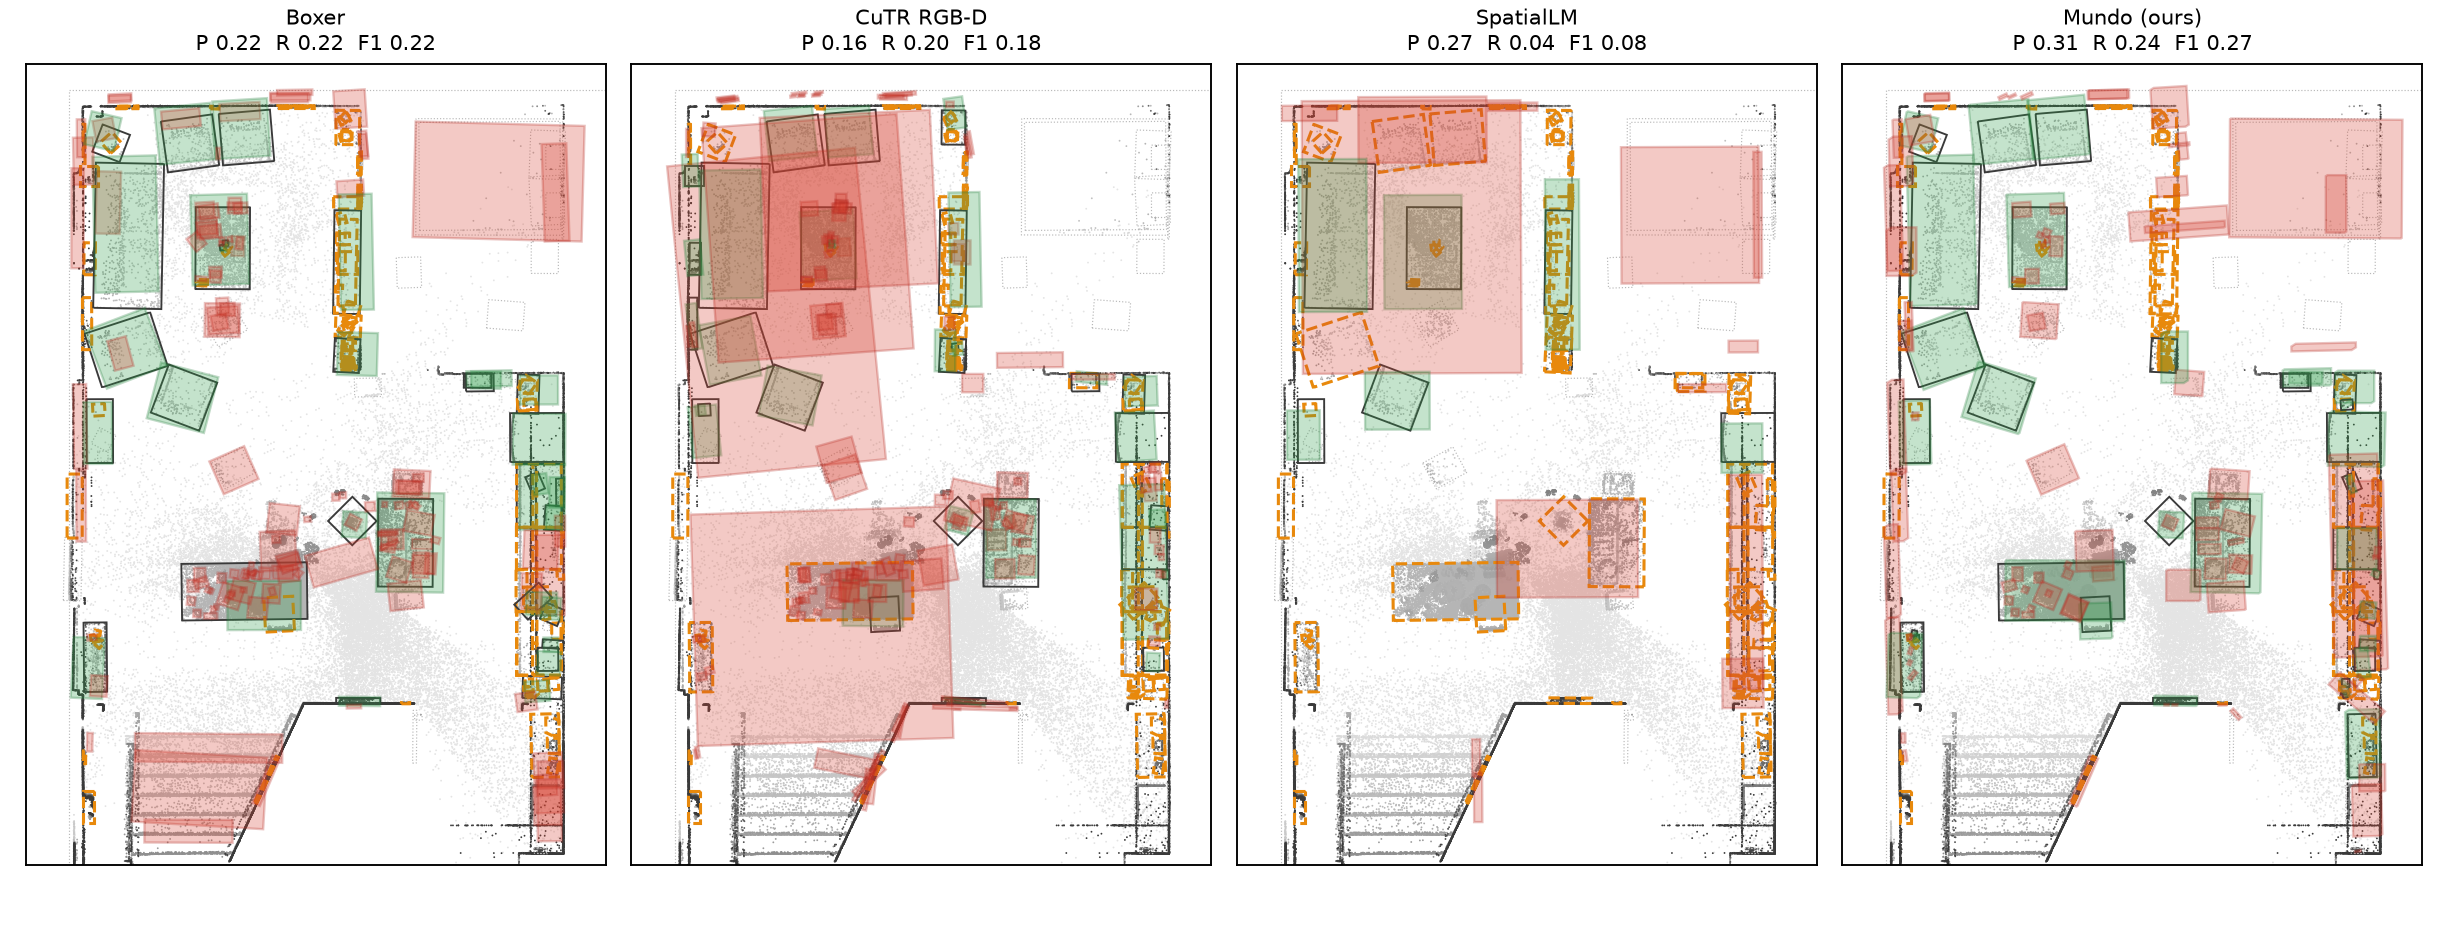
Per-sequence results
F1 at IoU 0.25 for each sequence, with F1 at IoU 0.5 as the smaller grey number. Boxer and CuTR RGB-D are shown at their best-F1 thresholds, Mundo as the mean over runs.
| Sequence | frames | GT | Boxer A | CuTR A | Ours A | Boxer B | CuTR B | Ours B |
|---|---|---|---|---|---|---|---|---|
| ca1m 45662921 | 115 | 190 | 0.38 0.12 | 0.43 0.21 | 0.46 0.20 | 0.30 0.11 | 0.28 0.10 | 0.42 0.18 |
| ca1m 45261179 | 31 | 68 | 0.51 0.23 | 0.49 0.32 | 0.49 0.26 | 0.41 0.19 | 0.41 0.20 | 0.45 0.20 |
| ca1m 47115543 | 70 | 83 | 0.36 0.23 | 0.46 0.26 | 0.50 0.28 | 0.35 0.22 | 0.43 0.20 | 0.55 0.27 |
| ca1m 45261143 | 66 | 75 | 0.31 0.21 | 0.37 0.21 | 0.43 0.24 | 0.30 0.15 | 0.37 0.15 | 0.47 0.24 |
| ca1m 45261615 | 52 | 83 | 0.49 0.29 | 0.58 0.28 | 0.53 0.27 | 0.43 0.22 | 0.45 0.18 | 0.49 0.24 |
| ca1m 42897545 | 35 | 54 | 0.46 0.28 | 0.53 0.34 | 0.59 0.32 | 0.43 0.16 | 0.54 0.14 | 0.52 0.16 |
| ca1m 45261133 | 144 | 103 | 0.43 0.26 | 0.39 0.22 | 0.52 0.33 | 0.43 0.25 | 0.46 0.21 | 0.57 0.33 |
| ca1m 42897552 | 18 | 58 | 0.51 0.27 | 0.46 0.27 | 0.49 0.23 | 0.50 0.16 | 0.35 0.18 | 0.43 0.19 |
| ca1m 45663113 | 39 | 82 | 0.41 0.22 | 0.45 0.22 | 0.44 0.25 | 0.32 0.13 | 0.43 0.22 | 0.41 0.20 |
| ca1m 42897521 | 59 | 60 | 0.52 0.29 | 0.58 0.45 | 0.71 0.40 | 0.50 0.24 | 0.55 0.44 | 0.74 0.39 |
| adt seq106 | 92 | 135 | 0.30 0.18 | 0.30 0.08 | 0.37 0.19 | 0.22 0.09 | 0.18 0.05 | 0.27 0.11 |
Reproduction check
Scene-level class-agnostic mAP over IoU 0.05 to 0.50 for the baselines in track A, which matches the input of the RGB+D rows in Boxer Table 3 [1]. The orders of magnitude agree, with higher values on CA-1M and lower values on ADT. Our CuTR run uses its own detector instead of OWLv2 boxes, and CA-1M is its training domain. The scene-level GT filtering of the paper is not published, so exact agreement is not expected.
| Method | Data | mAP, this protocol | mAP, Boxer paper |
|---|---|---|---|
| Boxer (OWLv2 + BoxerNet), RGB-D | CA-1M | 0.294 | 0.204 |
| Boxer (OWLv2 + BoxerNet), RGB-D | ADT | 0.135 | 0.215 |
| CuTR RGB-D | CA-1M | 0.401 | 0.178 |
| CuTR RGB-D | ADT | 0.160 | 0.198 |
| CuTR RGB | CA-1M | 0.164 | 0.064 |
| CuTR RGB | ADT | 0.001 | 0.004 |